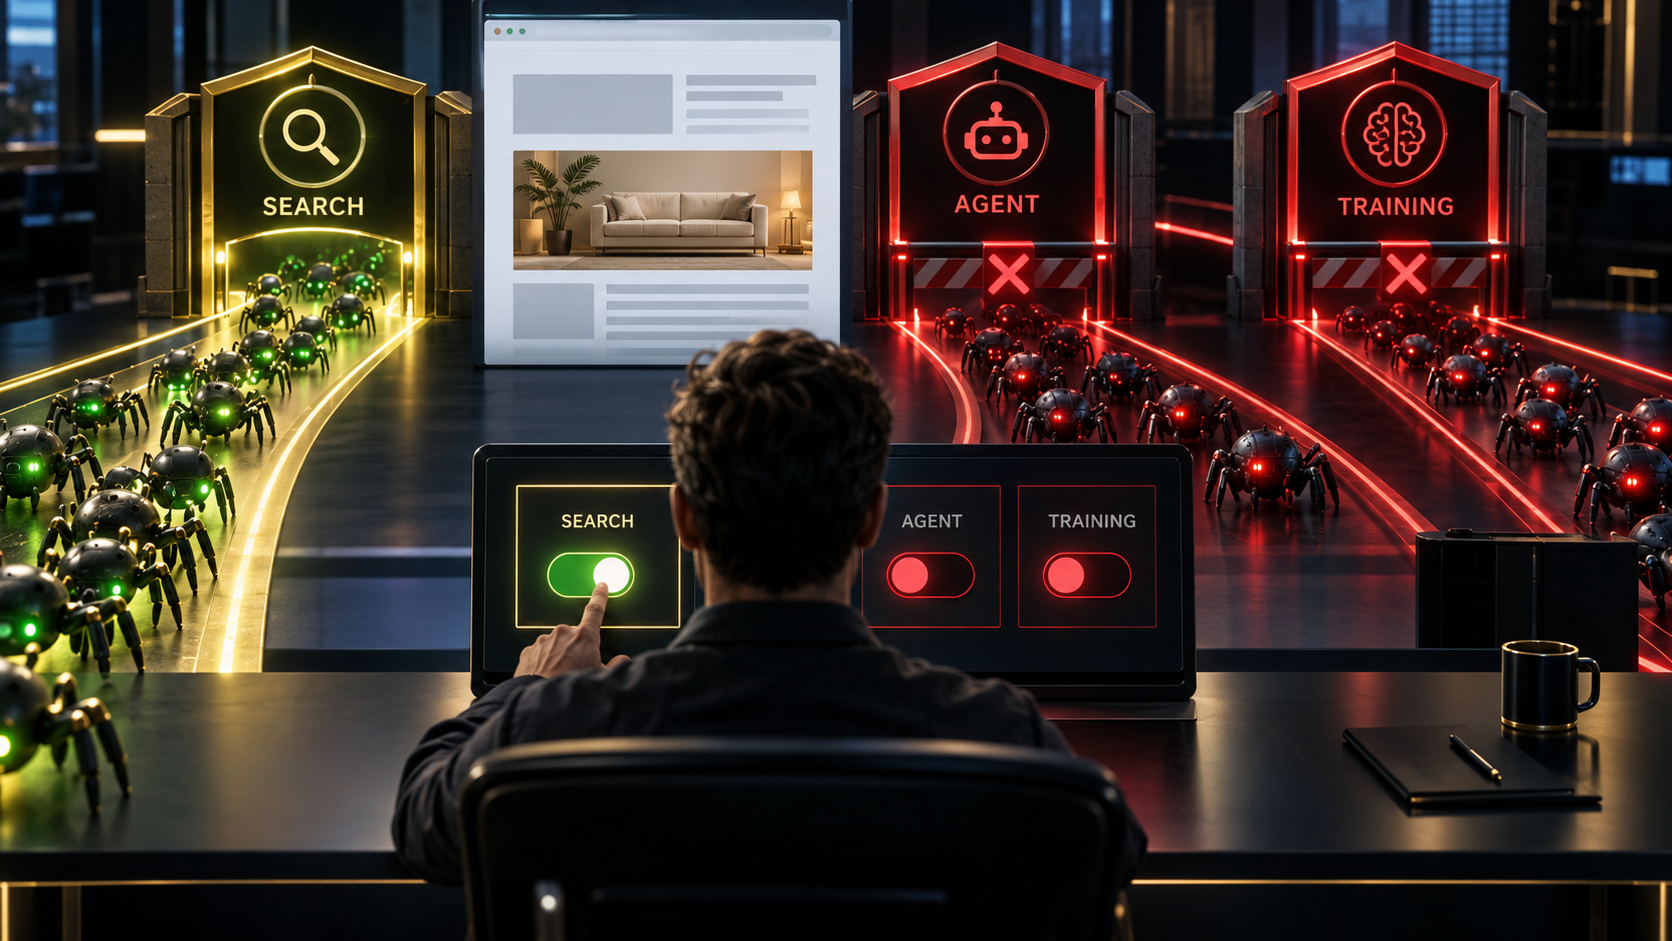
Cloudflare's new AI crawler defaults take effect on 15 September 2026. New domains joining Cloudflare will block Training and Agent bots on pages that display adverts while continuing to allow Search crawlers.
The important detail is that some crawlers serve more than one purpose. Cloudflare says mixed-purpose crawlers that combine Search and Training will now be judged by the most restrictive rule, so a website that blocks Training may also block Googlebot, Applebot or BingBot.
For a publisher, shop or small-business website, this creates a real choice between controlling how content is used and protecting discoverability. The right response is to check the setting, understand the trade-off and monitor actual crawl traffic rather than blindly choosing the strictest option.
What changed on 15 September?
Confirmed fact: Cloudflare now classifies important automated traffic by behaviour. Search crawlers index content so it can appear in search results. Agent bots visit in real time on a person's behalf, while Training crawlers collect content to train or fine-tune AI models.
For new domains onboarding to Cloudflare, the new default blocks Training and Agent traffic on pages that display adverts but leaves Search allowed. Existing customers can manage the same controls, including customers on Cloudflare's Free plan.
Cloudflare offers three choices for each behaviour: block it across the entire website, block it only on pages where adverts are detected, or allow it. The previous single Block AI bots switch is being deprecated as these more specific controls take over.
- Search: crawlers that index content for later answers or results
- Agent: automation visiting a page for a person in real time
- Training: crawlers collecting content for model training
- Controls: block everywhere, block on pages with adverts, or allow
- Availability: all Cloudflare customers, including the Free plan
The mixed-purpose crawler warning
Confirmed fact: Cloudflare says a crawler can belong to more than one category. From 15 September, a mixed-purpose crawler that performs both Search and Training is affected by every rule that applies to it.
The most restrictive rule wins. If Search is allowed but Training is blocked, Cloudflare says mixed-purpose crawlers such as Googlebot, Applebot and BingBot will be blocked. That includes websites using the legacy Block AI bots option unless the owner selected a different preference before the change.
This does not mean every Cloudflare website disappears from Google today. It means the result depends on the domain's settings, the page and how Cloudflare classifies the visiting crawler. Website owners should verify their own configuration instead of relying on a general headline.
Why this matters to small businesses and creators
Our analysis: a small website normally wants two things that can now pull in different directions. It wants search engines and useful assistants to find its pages, but it may not want every article, product image or paid resource collected for model training without a clear benefit.
Search visibility can bring readers, enquiries and sales. Blocking a mixed-purpose crawler without understanding the effect could reduce that route to the business. Allowing everything, however, gives the owner less control over how original material is collected and reused.
The practical advantage of Cloudflare's new system is not that it makes the decision automatically. It exposes the purpose of more bot traffic and gives the website owner separate controls instead of one blunt switch.
The opportunity: AI traffic audits become a useful service
Most small-business owners will never study crawler classifications, security rules and referral data. A freelancer or agency can turn that confusion into a simple fixed-price website service: record the current settings, protect valuable pages, preserve wanted search access and create a short monitoring report.
The service should not promise higher rankings or payments from AI companies. Its value is controlled access and evidence. The client receives a one-page policy explaining which automated visitors are allowed, which are blocked and what metric will trigger a review.
Creators can also use the change to classify their own content. A public tutorial designed to attract readers may need different access rules from a paid download, members-only resource or archive of original photography.
- Audit current AI crawler and legacy bot settings
- Separate discovery pages from valuable protected content
- Record search, agent and training decisions in plain English
- Check referral and crawler data after every rule change
- Offer a monthly review as classifications and bots evolve
Risks and limitations
The biggest risk is treating all bots as identical. A Training block can affect a crawler that also supports search, while an Agent block may stop an AI assistant from visiting a product page on behalf of a potential customer.
Cloudflare's controls apply only to traffic passing through Cloudflare and detected under its classifications. They do not create a universal legal licence, guarantee that every scraper is identified or replace copyright advice.
Blocking a crawler also does not guarantee compensation. Cloudflare is developing paid-access models and partnerships, but an ordinary website owner should not expect today's setting change to produce automatic income.
Finally, changing security controls without a baseline makes the result hard to judge. Record current organic visits, indexed pages, referrals and crawl errors before making a major restriction, then compare like with like.
A practical 30-minute website check
If you control a Cloudflare account, open Security Settings and choose Configure AI bot policies. Record the current Search, Agent and Training choices before changing anything. If a host or website platform manages Cloudflare for you, ask what policy applies to your domain and whether mixed-purpose search crawlers are affected.
Decide the job of each important page. A blog article intended to win organic traffic may justify different access from a paid course, customer portal or original asset library. Avoid blanket rules until you can explain what useful traffic they may remove.
After any change, inspect Google Search Console for crawl or indexing problems and check analytics for organic and referral movement. Put a review date in the calendar for seven days later. If discovery falls sharply, investigate the crawler rule before assuming the content itself has failed.
- Screenshot the current policy before editing it
- Confirm whether the legacy Block AI bots switch was enabled
- Keep Search access unless you have a measured reason to block it
- Review mixed-purpose crawler treatment carefully
- Monitor indexing, crawl errors and referral traffic for seven days
COMMON BEGINNER QUESTIONS
Does Cloudflare now block every AI crawler?
No. The policy has separate controls for Search, Agent and Training behaviours. New domains block Agent and Training bots on pages with adverts by default while Search remains allowed.
Can blocking AI training affect Google Search?
It can affect mixed-purpose crawlers. Cloudflare says Googlebot, Applebot and BingBot may be blocked when a website blocks Training because those crawlers are classified as serving both Search and Training purposes.
Are the AI crawler controls available on Cloudflare's Free plan?
Yes. Cloudflare says all customers, including Free-plan users, can manage Search, Agent and Training traffic by behaviour.
Where are the settings in Cloudflare?
Cloudflare directs customers to Security Settings and then Configure AI bot policies. A managed hosting provider may control these settings on the website owner's behalf.
Will blocking AI crawlers make money for my website?
No automatic payment is created by this setting. Cloudflare is developing paid-access partnerships, but ordinary website owners should treat crawler controls as an access decision, not guaranteed income.
Loading comments...